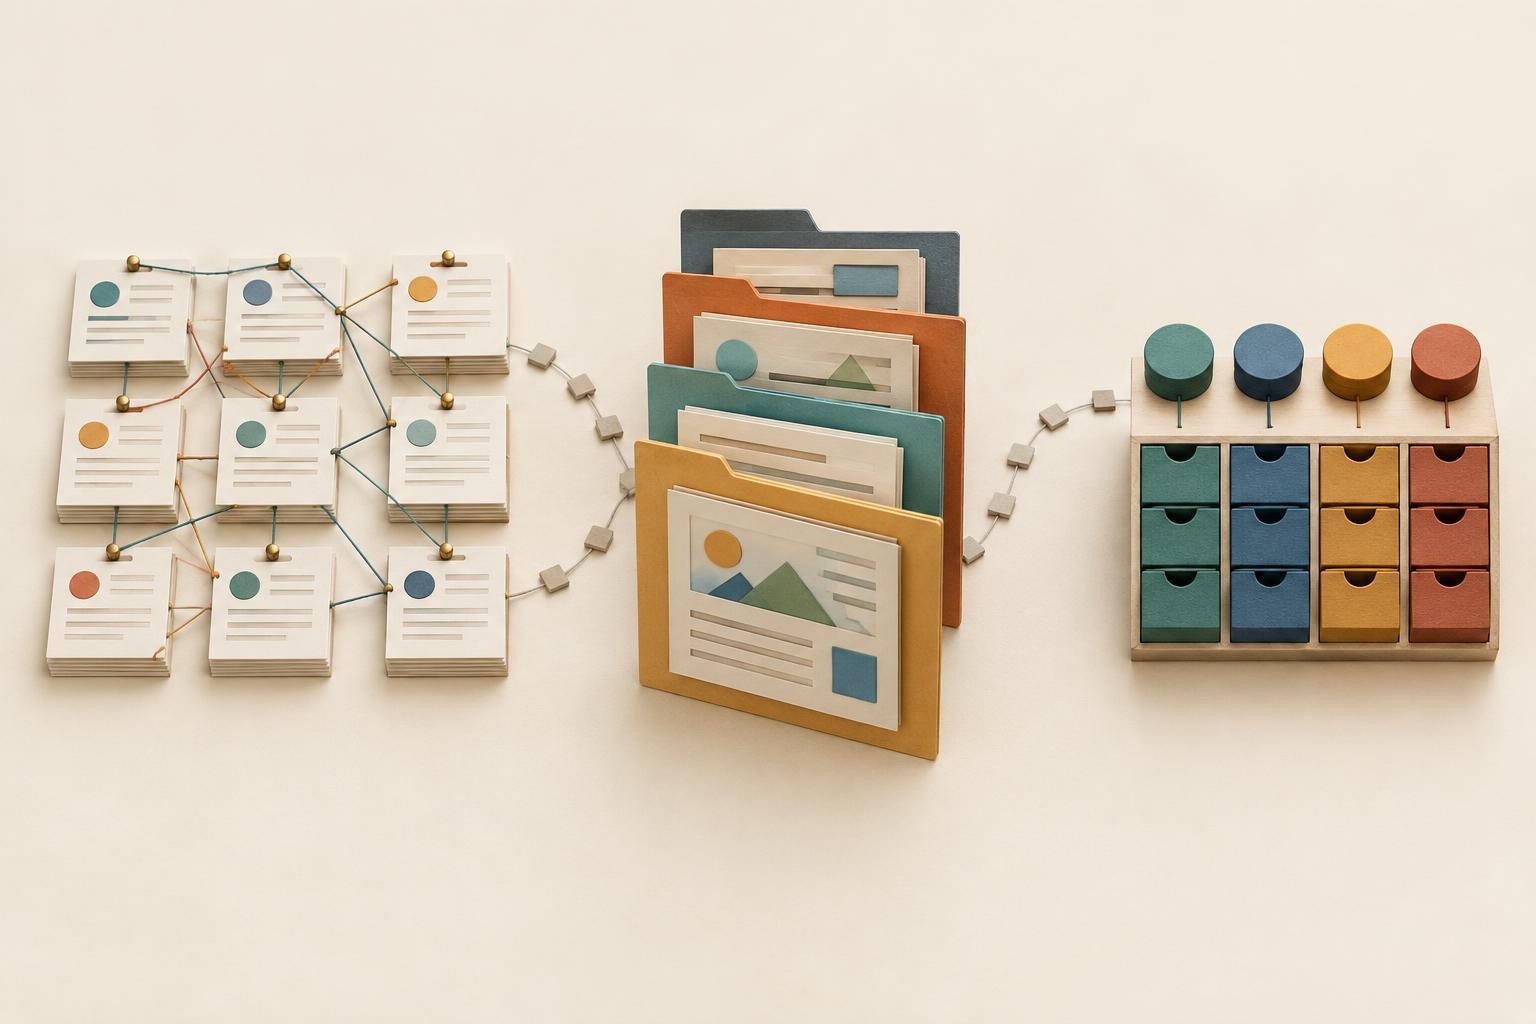
Start with the work your data must do
Database choices become easier when you begin with operations rather than product names. What will the application need to retrieve: one record by ID, all orders for a customer, or a report combining several kinds of records? Which fields must be searchable? What changes together, and what happens if an update stops halfway through? Write down a few common reads and writes before deciding how to store the data.
Relational, document and key-value databases describe different ways to organize and access information. None is automatically best for a small or large application. A store that makes one operation simple may make another awkward. The goal is to choose a model that fits the application’s important access patterns while leaving room for changes you can reasonably anticipate.
Relational databases: useful when connections matter
A relational database organizes data into tables with defined columns. Records can refer to records in other tables: an order might identify a customer, while order items identify both an order and a product. Queries can combine those tables, filter results and calculate summaries. This makes the model a strong starting point when relationships are important or when users will ask varied questions of the same data.
Consider a booking system. It may need to find available slots, create a booking and prevent conflicting assignments. Relational databases commonly provide transactions that group related changes so they succeed or fail together. Constraints can also help enforce rules, such as requiring every booking to reference an existing account. The exact guarantees and features depend on the database and its configuration.
The trade-off is that tables, relationships and schema changes require planning. Complex joins can demand careful indexing and query design as data grows. That is not a reason to avoid relational databases; it is a reason to test the queries the application will actually run.
Document databases: useful for self-contained records
A document database stores records as documents, often with nested fields and arrays. A product listing, for example, could keep its name, descriptions, attributes and images together. Retrieving the listing may then require one document read rather than combining several tables. Documents can also accommodate variations: a bicycle and a laptop might have different attributes without needing identical fields.
This flexibility does not remove the need for data design. If customer details are copied into many order documents, changing an address in one place will not necessarily update the copies. If a document grows to include a long history of events, routine reads may carry more data than they need. Decide which information belongs together based on how it is read and updated, not merely because it can be nested.
Document databases differ in their support for indexes, queries and transactions. Check whether a candidate can efficiently answer your required searches and enforce the update behavior you need. A flexible document shape is valuable when records vary, but it is less helpful if the application mostly needs to combine and reconcile information across many record types.
Key-value databases: useful when the lookup is known
A key-value database stores a value under a unique key. Given the key, an application retrieves or replaces the associated value. This is a natural fit for operations such as looking up a session by its identifier or retrieving precomputed settings for an account. The simple access pattern can be appealing when the application already knows exactly what it needs.
The limitation appears when the question changes. If values are stored under session IDs, finding every session belonging to a particular account may require an additional index or a separate data structure. Searching inside values and combining records may be limited or unavailable, depending on the system. Expiration features, persistence and replication behavior also vary, so do not assume that every key-value store is suitable as the sole durable copy of important data.
Key-value storage often works alongside another database. For example, an application might keep authoritative account records in a relational database and use a key-value store for temporary session data. Give each store a clear role so the team knows which copy to trust.
Make the decision with a small workload sketch
List your main records, then write five to ten representative operations in plain language. Include reads, writes, searches and updates that span multiple records. Mark which operations must be correct together and which can tolerate a delay before a new value appears elsewhere. Next, sketch each candidate model and note where it needs joins, duplicated data, extra indexes or application-side coordination.
Try the hardest two or three operations with realistic sample records before committing. Check not only whether a query is possible, but whether the team can understand and maintain it. Also consider backups, access controls, monitoring and recovery: a familiar database with good operational support may be a better fit than a theoretically elegant model that your team cannot comfortably run.
If you are unsure, choose the simplest design that handles your essential queries and correctness requirements. You can introduce another store later for a specific need, but every additional database adds data synchronization and maintenance work. Let demonstrated access patterns, rather than the label on the database, drive the choice.


