Why split a table?
As a table grows, some work can become harder to manage. Queries may scan more rows than necessary, indexes can take more space, and maintenance tasks such as deleting old records may become cumbersome. Splitting the data can make certain operations more targeted. It does not, by itself, make every query faster: the benefit depends on how the data is divided and how applications access it.
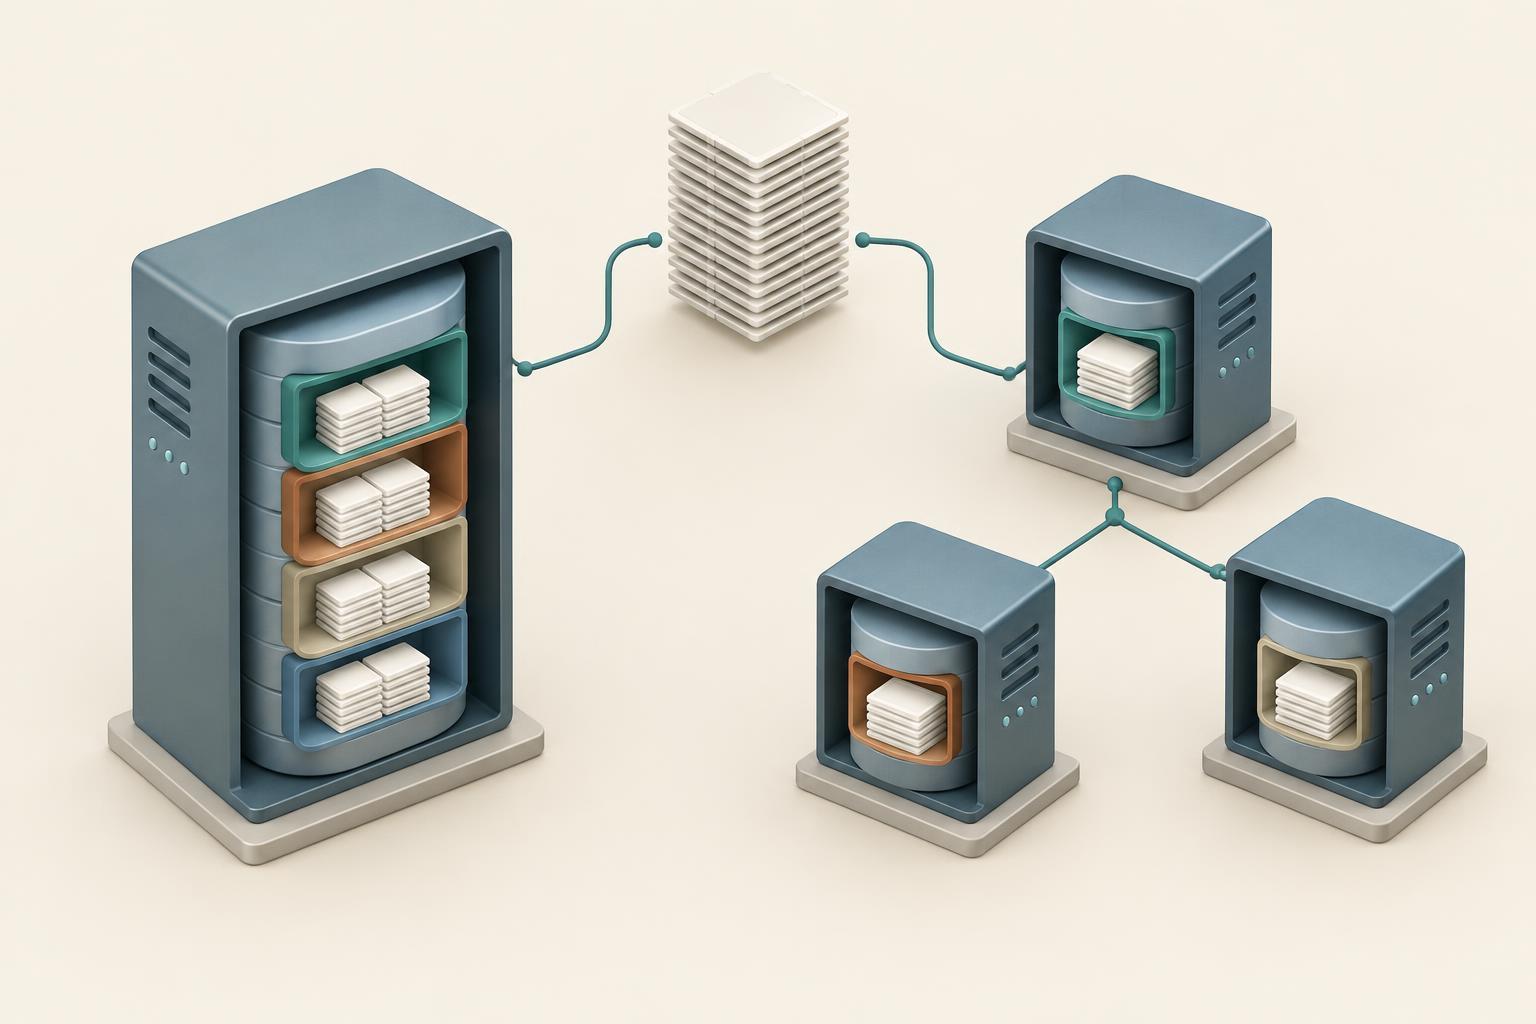
Partitioning and sharding both assign rows to smaller groups, but they usually solve problems at different levels. Partitioning commonly divides one logical table within a database system. Sharding distributes data across separate database instances. The terms can overlap: a shard may contain partitioned tables, and some systems use “partition” to describe a distributed unit. When evaluating a design, ask where the data lives, who decides where a row goes, and what happens when a query needs multiple groups.
Partitioning: smaller pieces of one logical table
With table partitioning, an application can often continue querying a single table name while the database stores its rows in separate partitions. For example, an events table might be divided by month using an event_time column. A query restricted to one month may read only the relevant partition if the database can use that filter to exclude the others. This is often called partition pruning.
Range partitions suit ordered values such as timestamps. List partitions group specified values, such as regions, while hash partitions distribute rows according to a key. The available methods and their behavior vary by database. A useful partition key matches common filters and keeps partitions manageable. If most queries filter by customer_id but the table is partitioned only by event_time, those queries may still touch many partitions.
Partitioning can also simplify some lifecycle tasks. Dropping an old time-based partition may be easier than deleting its rows individually, provided that retention requirements and dependencies allow it. It is not a substitute for checking query plans, indexes, or schema design, and partitioned tables may come with constraints on keys, indexes, and maintenance operations.
Sharding: distributing data across databases
Sharding places subsets of data on separate database instances, often running on different servers. A customer-facing service might assign each customer_id to a shard and send that customer’s reads and writes to the same database. The application, a routing layer, or a database platform must determine the destination for each request.
Sharding can spread storage and traffic beyond one database instance, but it adds coordination work. A query for one customer may be straightforward if the shard key is known. A report covering every customer may need to query all shards and combine the results. Joins and transactions involving rows on different shards can also become more complicated than their single-database equivalents.
Choosing a shard key is a long-lived decision. A simple hash of customer_id may spread customers across shards, yet a few unusually busy customers could still create hotspots. Adding shards later may require moving data and updating routing rules. Designs that use an indirection layer, such as a mapping from customers to shards, can offer flexibility, but that mapping becomes infrastructure that must remain accurate and available.
The practical difference: what stays local?
Consider a table of orders. Partitioning it by order date can help a database narrow a query for last week’s orders and manage older records. Sharding it by customer_id can distribute customers across database instances. These choices address different access patterns: a date filter helps find a partition, while a customer ID helps find a shard. Using both is possible, but a query for all orders from last week may still need to visit every shard, even if each shard prunes its local partitions.
A good split therefore starts with the workload, not just the row count. Identify the queries and writes that cause difficulty, the filters they use, and the operations that must stay together. Ask whether the proposed key distributes work evenly and whether important requests can identify their destination without scanning many groups.
A sensible order of decisions
Before introducing either approach, examine slow queries, appropriate indexes, unnecessary data retention, and whether routine maintenance is keeping pace. If the main need is to manage a large time-based table or skip irrelevant ranges within one database, partitioning may be the simpler next step. If one database instance cannot comfortably serve the required storage or traffic, sharding may be worth its added operational cost.
Whichever route you choose, test it with representative queries and data distribution. Plan for rows that arrive late, keys that are missing or change, growth that is uneven, and backups and restores. The goal is not merely to create smaller pieces. It is to make the common work easier while keeping routing, maintenance, and recovery understandable as the system grows.


