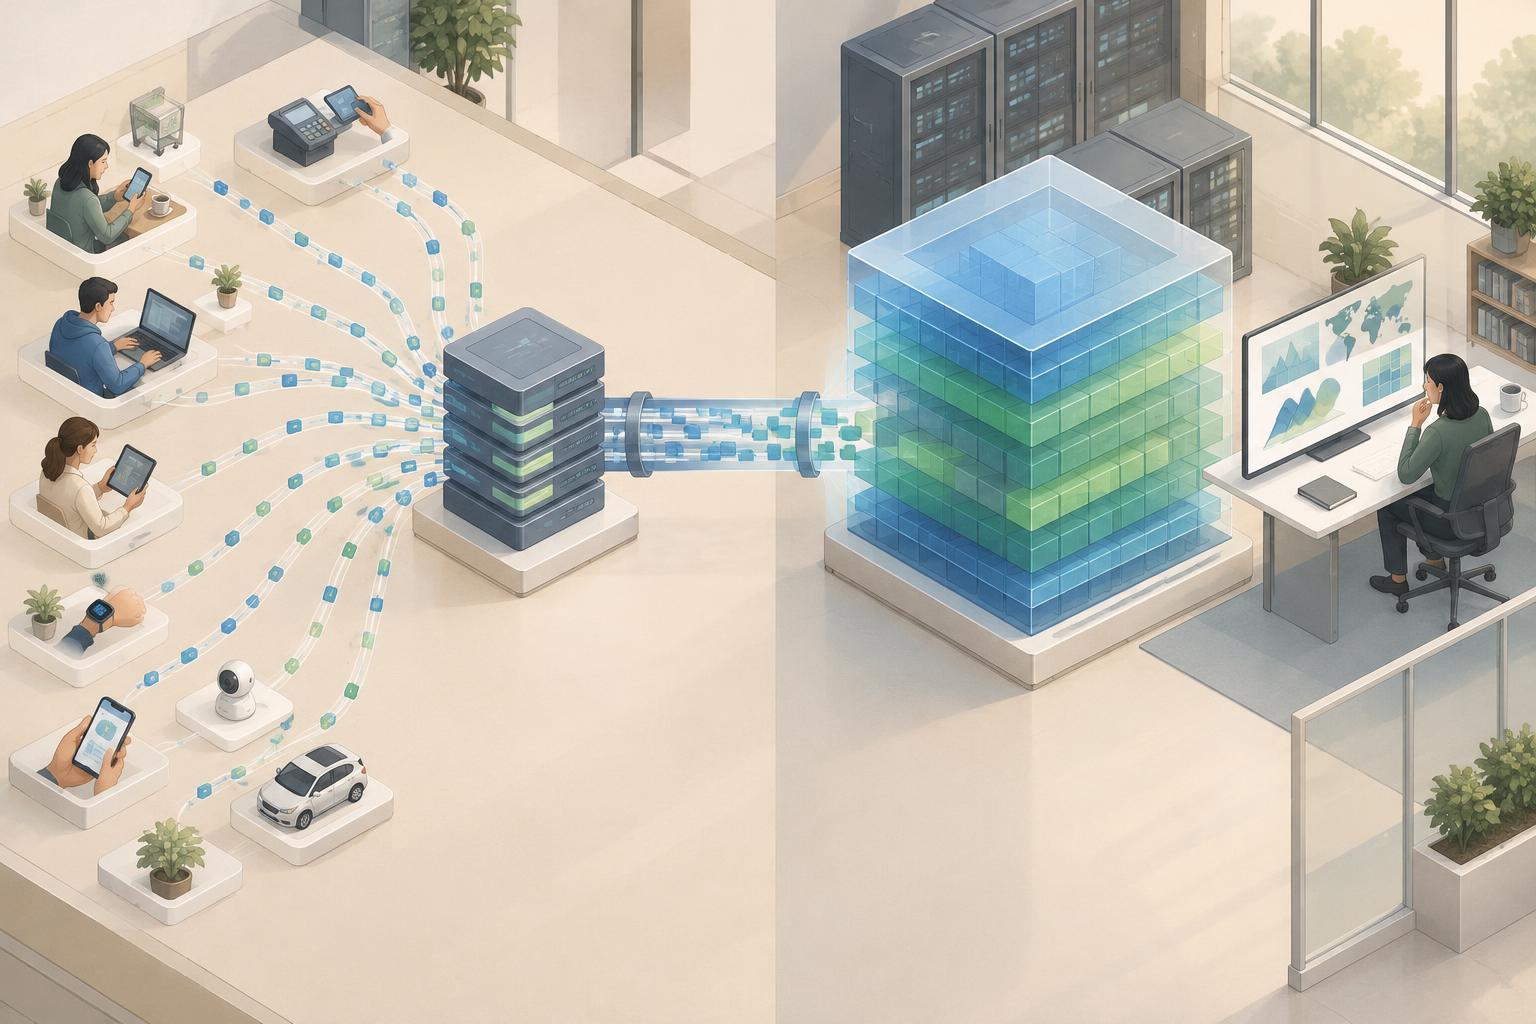
Two workloads, two kinds of questions
A customer places an order. The application needs to check inventory, record the purchase, and return a result promptly. Later, a manager asks which product categories sold best across several months. Both questions concern the same business, but they put different demands on its data infrastructure.
Online transaction processing, or OLTP, supports operational actions such as creating an order, updating a profile, or recording a payment status. Its queries commonly read or change a small number of records, and many users may submit them at once. Online analytical processing, or OLAP, supports comparisons, summaries, and exploration across larger sets of records. An analytical query might group orders by region and month or join sales data to a product catalog.
The distinction describes workloads, not a rule that every organization needs two databases. A small application may handle both kinds of query in one system. As data and usage grow, separating them can help prevent a large report from competing with customer-facing transactions for the same resources.
What transaction systems optimize for
An OLTP design puts reliable changes and predictable response times first. Consider a checkout operation that creates an order and reduces available stock. If one change succeeds and the other fails, the application needs a defined way to avoid leaving the records inconsistent. Database transactions provide tools for treating related changes as a unit, subject to the guarantees and configuration of the database in use.
Operational schemas often separate entities such as customers, orders, order items, and products into related tables. This can make individual facts easier to update without copying the same value into many places. Indexes then help the application find specific records, such as an order by its ID. Indexes are not free, though: each additional index can add work when rows are written.
A useful OLTP design exercise is to list the application's critical actions. For each one, identify the records it reads, the records it changes, the consistency it requires, and the response time users can tolerate. That exercise is more informative than choosing a database based only on the amount of data it can store.
What analytical systems optimize for
Analytical queries tend to read many records while changing few or none. To answer “How did weekly sales vary by category?”, a system may scan a substantial portion of its order history, combine it with product information, and calculate totals. Design choices that help here can include column-oriented storage, precomputed summaries, and models organized around measurable events, such as sales, with related descriptive fields.
An analytical model may deliberately repeat some descriptive data or prepare it in advance to make common reports simpler and faster. That differs from an operational schema, where avoiding duplicate facts often helps keep updates manageable. Neither layout is universally better; each makes a trade-off for the questions it must answer.
Analysis also needs definitions. If one dashboard counts canceled orders and another excludes them, the resulting totals may disagree even when both queries run correctly. Before tuning a report, define its measures, filters, time boundaries, and treatment of missing or changed records.
Moving data between the two
When workloads are separated, data has to travel from the operational system to the analytical one. Teams may copy it in scheduled batches, capture changes as they occur, or use a managed pipeline. The choice affects how fresh a report can be. A daily batch may suit a monthly review; a dashboard used to monitor today's orders may need more frequent updates.
A copied record also needs context. An order can be created, amended, and canceled, so an analytical pipeline must decide how to represent those changes. It should handle retries without silently counting the same event twice and provide a way to check that expected records arrived. These concerns do not disappear when a tool automates the transfer.
Separating systems introduces costs: another data model, pipeline monitoring, access controls, and potentially duplicated storage. It can also create a delay between an operational change and its appearance in a report. Make that delay visible to readers of the report rather than implying that every number is instantaneous.
Choosing a practical starting point
Start with the queries people actually run. If a small team needs occasional summaries over a modest order table, an indexed operational database and carefully scheduled reports may be sufficient. If reports routinely scan large histories, slow down checkout, or require extensive historical modeling, a separate analytical environment becomes easier to justify.
For the order example, keep the checkout path focused on safely recording the transaction. Then decide how the sales report should receive its data and how recently it must be updated. Test both paths: a fast dashboard is little comfort if it disrupts orders, while a responsive checkout does not make an inaccurate report useful.
OLTP and OLAP are best treated as design lenses. One asks, “Can the system record this action correctly and promptly?” The other asks, “Can people learn reliably from many recorded actions?” Answer those questions first, then choose the storage, modeling, and data movement that fit.


