Start with how the application uses data
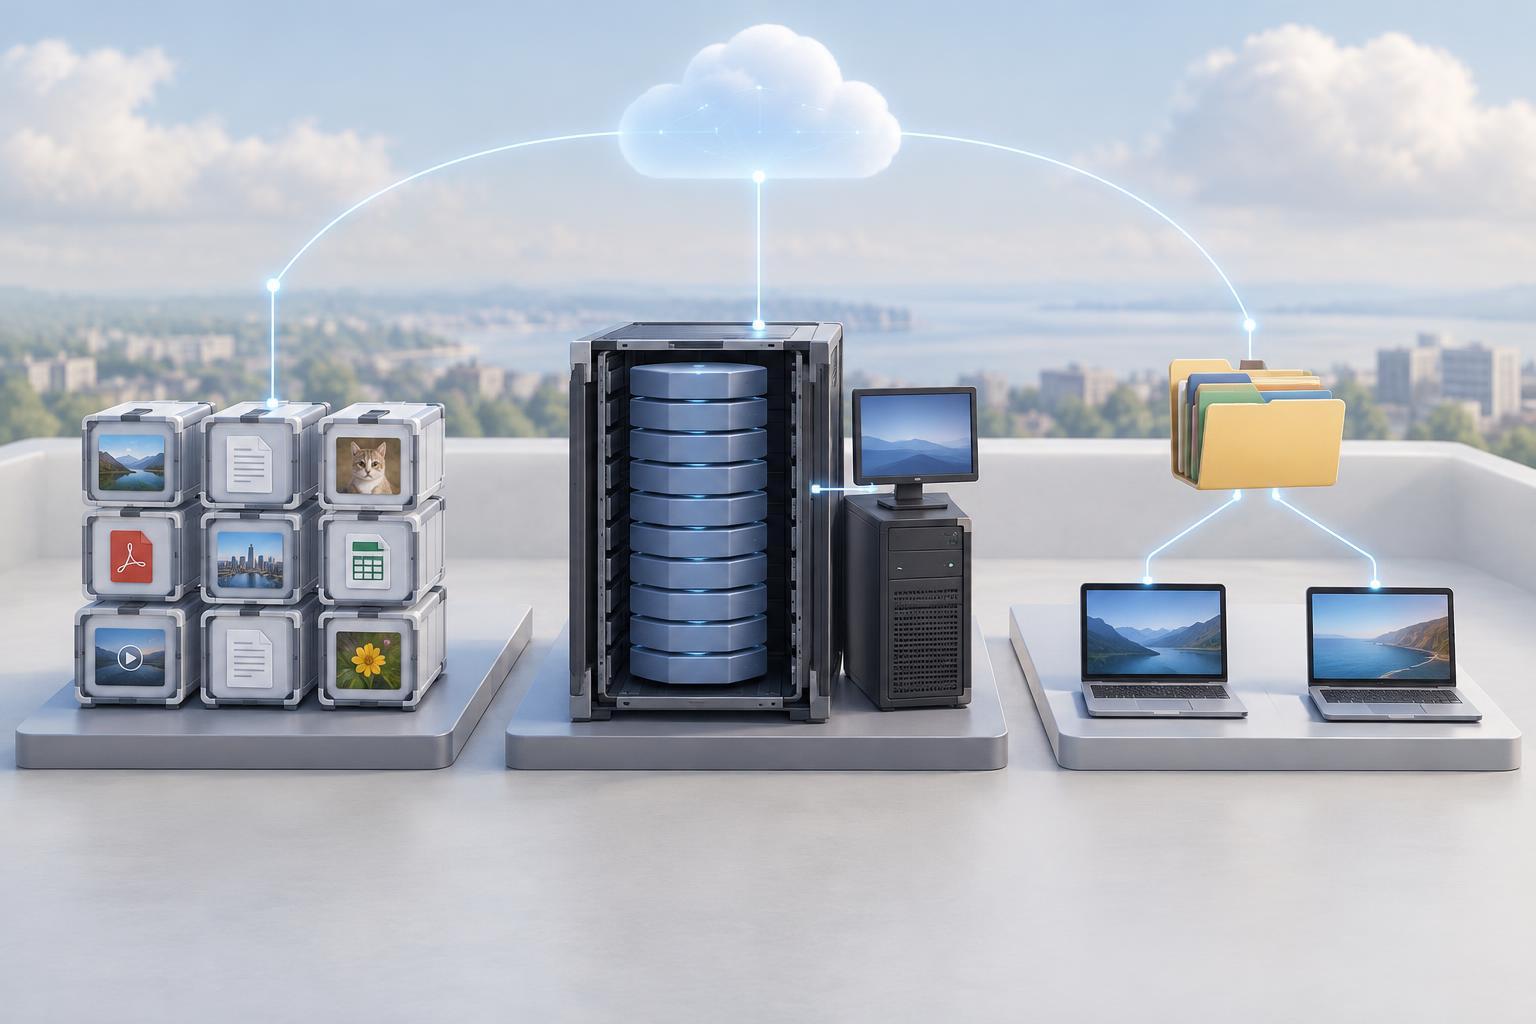
Choosing cloud storage begins with a question: how does the application expect to read and write data? A website serving uploaded photos, a database updating records and a team sharing design files may all need storage, but they interact with it in different ways. Object storage works with named objects through an API. Block storage presents a volume that a machine can format and use like a disk. File storage presents folders and files through a shared file system.
These categories describe access models, not guarantees about speed, price or safety. Cloud services within the same category can differ in capacity limits, performance options and management features. First identify what the software requires; then compare the available services on measurable needs such as latency, throughput, permissions, backup and cost.
Object storage: data addressed through an API
Object storage keeps each item as an object containing data, an identifier and usually metadata. Applications typically upload and retrieve objects using API requests rather than opening them as files on a local disk. A bucket might contain product images, log archives or downloadable documents. An application can store an object's identifier in its database and use that identifier when it needs the content.
This model fits data that is commonly written as a complete item and read later. It is useful when many application instances need access without coordinating writes to a shared disk. Metadata and lifecycle controls can also help organize large collections. However, object storage is not generally a drop-in replacement for a file system: software that expects to edit bytes in place, rename files atomically or lock open files may need a different design.
For example, a photo-sharing application might accept an upload, save the image as an object and keep its identifier alongside the user's post. If the application later creates a smaller preview, it can save that preview as a separate object. This approach avoids treating the image collection as a directory mounted on one server.
Block storage: a volume for a machine
Block storage supplies raw storage space in addressed blocks. After attaching a volume to a compute instance, you normally create a file system on it or let an application manage the blocks directly. To the operating system, it behaves much like a disk. That makes it a common fit for workloads that expect ordinary disk operations, including database servers and virtual machine boot volumes.
Block storage gives the attached system control over its file system and data layout, but that control comes with responsibility. The team still needs to consider file-system maintenance, capacity, backups and recovery. A volume is not automatically a shared folder: attaching or writing to the same storage from multiple machines requires explicit support and coordination. Without that, concurrent writers can corrupt data.
Suppose a small team runs a relational database on a virtual machine. A block volume may be suitable for the database files because the database needs frequent, targeted reads and writes. Choosing a volume should still involve checking the database's performance needs and planning how to restore both data and configuration if the machine fails.
File storage: shared folders and familiar paths
File storage organizes data into directories and files and exposes them through a file-sharing protocol. Applications can often use familiar paths and operations such as opening, listing and renaming files. Managed cloud file services are useful when several machines need to work with a shared set of files, particularly when existing software already assumes a shared directory.
Convenience does not eliminate coordination problems. Two processes editing the same file still need a sensible approach to locking or versioning. Performance can also vary with the number and size of files, the pattern of reads and writes, and the network between clients and storage. Check whether the service supports the protocol, operating systems and permissions your applications need.
For example, a group of processing workers might read input files from one shared directory and place completed outputs in another. File storage can preserve that workflow with fewer application changes than moving to an object API. If workers mostly process independent uploads, though, object storage may offer a simpler way to separate each job's data.
Make the choice with a short workload checklist
Ask what interface the software requires: an object API, an attached disk or a shared file path? Then map its operations. Does it replace whole items, update small portions frequently or need several machines to see the same directory? Note expected data size, file count, read and write patterns, and tolerance for delay. A workload can use more than one type: a database on block storage can hold references to media in object storage.
Finally, check the operational details rather than assuming any storage type is inherently durable or secure. Decide who can access the data, how it will be encrypted if needed, what backups or version history are required, and how a restore will be tested. Compare charges for stored capacity, requests, data transfer and provisioned performance where applicable. The best choice is the one that fits the application's access pattern and leaves the team with a recovery plan it can actually operate.


