An index is a shortcut to rows
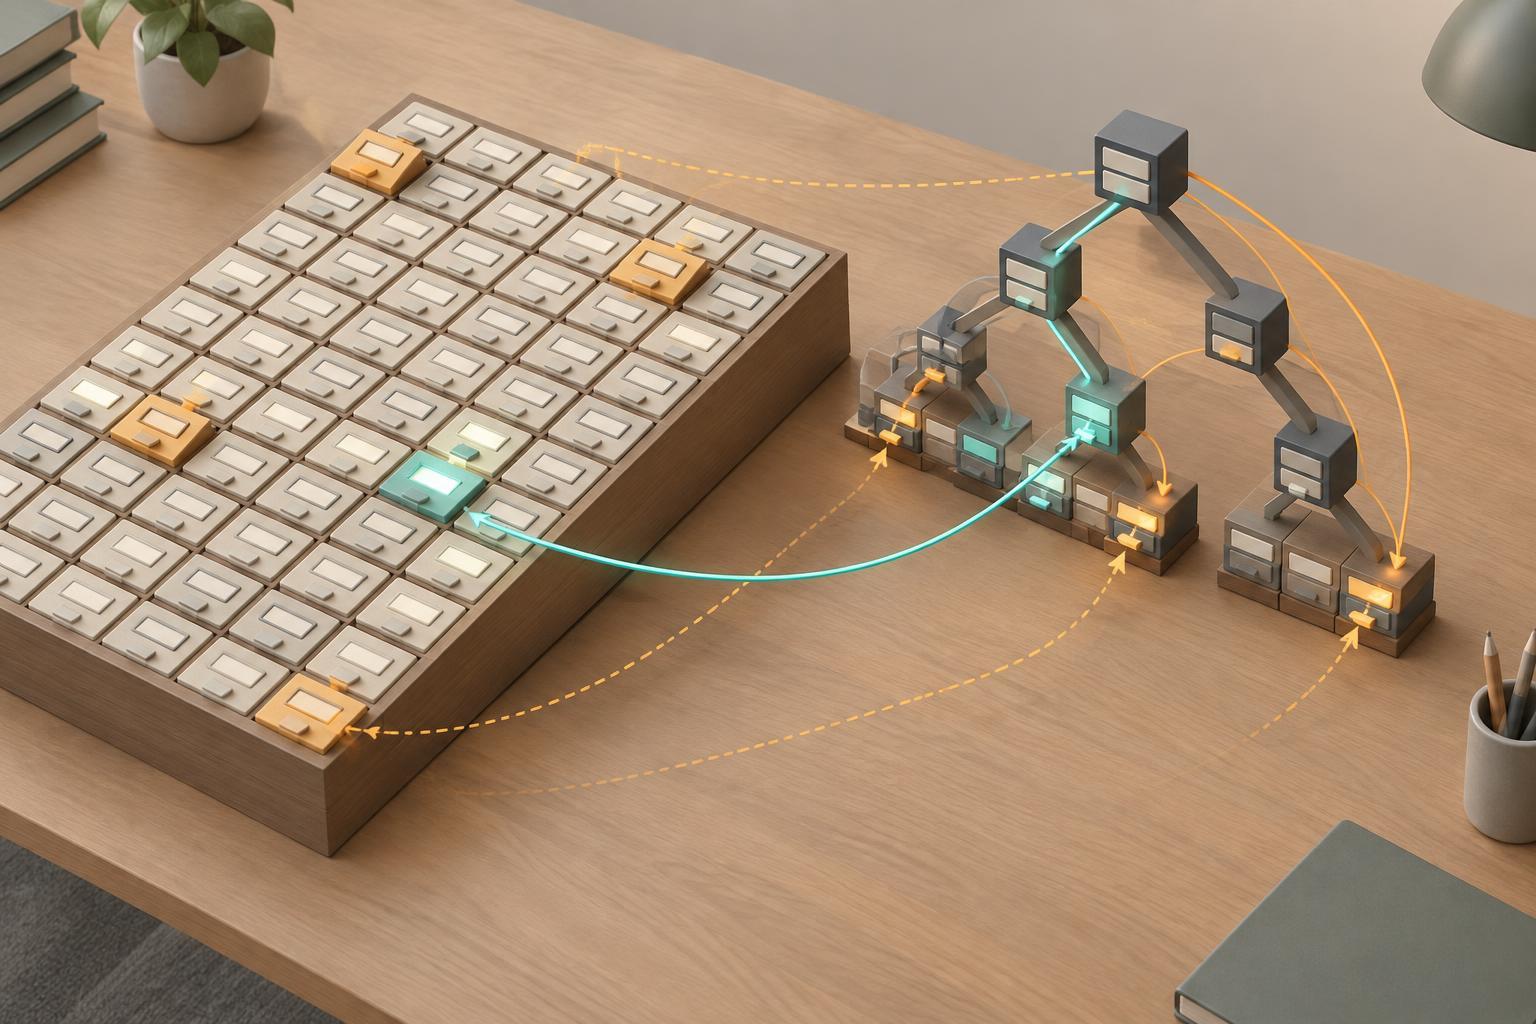
Imagine a table of orders with columns for an order ID, customer ID, status and creation time. To find one customer’s orders without a suitable index, a database may need to inspect every row. That is a table scan: reasonable for a small table, but potentially expensive as the table grows. An index gives the database another way to locate matching rows. It stores selected column values in a structure that points to, or otherwise identifies, the corresponding records.
Many relational databases commonly use B-tree-style indexes. Their ordered structure lets the database narrow its search rather than check every entry. An index on customer ID can help find one customer’s orders; an index on creation time can help find orders within a time range. The database may still need to fetch the full rows after finding matches. An index is therefore not a second copy of the entire table, and using one does not make every query fast.
Why some reads benefit more than others
Indexes are especially useful when a query needs a small portion of a large table. A lookup for a particular order ID is an intuitive example. They can also support joins, range filters and sorting when the indexed columns match the query. If an index supplies values in the order a query requests, the database may avoid a separate sort. If it contains every column the query needs, the database may be able to answer from the index without fetching full rows, depending on the database and its visibility rules.
Column order matters in a composite index. For example, an index on customer ID followed by creation time is often useful for finding one customer’s recent orders. It may be less useful for finding all recent orders across every customer. An index also offers less benefit when a filter matches most of a table: reading a large part of the index and then fetching many rows may cost more than scanning the table. The query planner estimates these costs and chooses an access path, which is why the presence of an index does not guarantee its use.
Every index adds work to writes
An insert does more than add a row to a table. The database must also add an entry to each relevant index. A delete must remove or invalidate entries, and an update may need to change them when indexed values change. Maintaining an ordered index can involve additional page writes and, at times, reorganizing pages. These operations consume storage and memory as well as input/output capacity. The exact cost depends on the database engine, index type and pattern of changes.
Consider an orders table with indexes on customer ID, status, creation time and several combinations of those columns. Those indexes may make particular searches convenient, but every new order creates multiple pieces of index work. A frequently changing status column can be especially costly to index if updates are common. Indexes can also affect bulk loads and compete with other data for cache space. This does not mean indexes are bad for write-heavy systems; it means each one should earn its maintenance cost by supporting queries that matter.
Choose indexes for queries, not columns
Start with a concrete query rather than a rule such as “index every column used in a WHERE clause.” Note its filters, join conditions, requested columns and sort order. Then consider how many rows it is likely to return. A filter that usually selects a small set of records is a stronger candidate than one that returns nearly everything. Check whether an existing composite index already supports the query before adding another with nearly the same columns.
It also helps to think about the table’s write workload. An index that saves time for a frequent, user-facing lookup may be worthwhile even if it slows inserts slightly. An index serving a rarely used report might not be, particularly on a table that changes constantly. Unique indexes have an additional purpose: they enforce that indexed values do not repeat, subject to the database’s handling of nulls. That correctness requirement may justify an index independently of its read performance.
Test the trade-off
Use your database’s query-plan tool to see whether a query scans the table, uses an index, sorts results or fetches many rows after an index lookup. Compare execution times using representative data and query parameters; a tiny test table can hide the value of an index, while an unusual parameter can make one plan look better than it normally would. If available, compare write throughput, storage use and cache behavior before and after the change.
Treat an index as a design choice that can be revisited. As tables and access patterns change, a once-useful index may become redundant, and a new query may need a different column order. The goal is not the largest possible collection of indexes. It is a small, deliberate set that makes important reads efficient while keeping writes, storage and maintenance within acceptable bounds.


