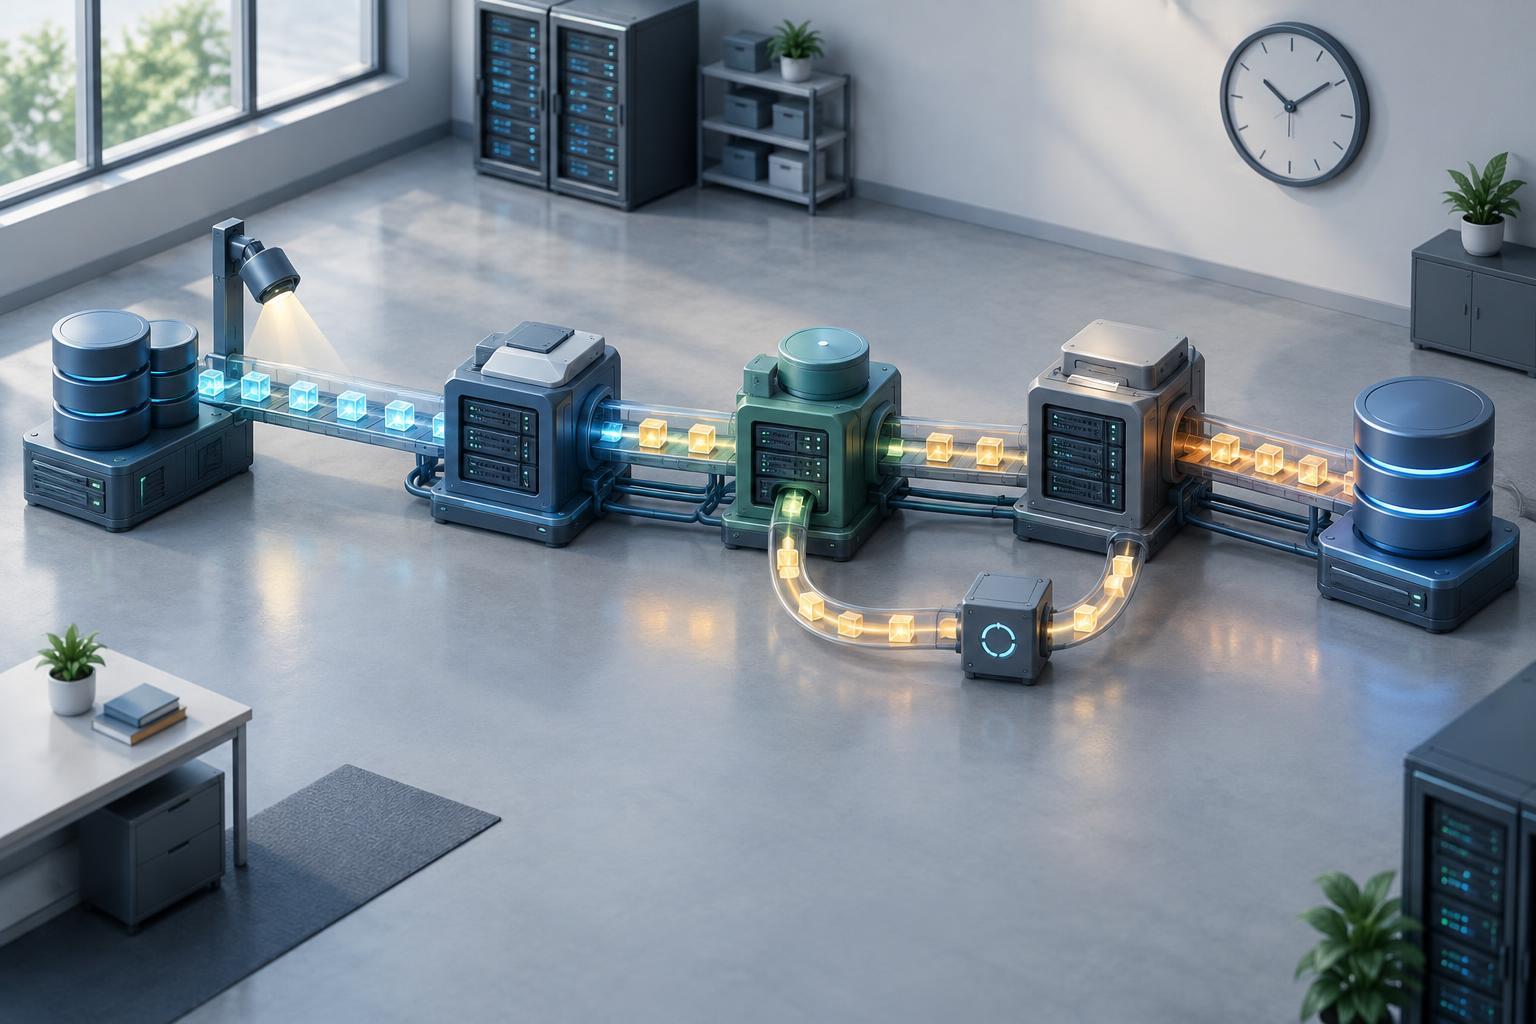
What an orchestrator does
A data pipeline moves information through steps such as extraction, validation, transformation and publishing. Orchestration coordinates those steps: it decides which task can run, when it can run and what should happen if it fails. The orchestrator does not necessarily process the data itself. It may start a database query, a container or a script, then record the result and trigger the next task.
Consider a small team preparing a daily sales summary. It first copies transactions from a source system, checks that the copy completed, calculates totals and publishes a table for a dashboard. Running all four tasks at the same time would risk calculating totals from incomplete data. An orchestrator represents their order explicitly and keeps a record of each run, so a failed step can be found and addressed without guessing which commands ran.
Model dependencies around usable data
A dependency means one task must reach an acceptable state before another begins. In a simple pipeline, validation depends on extraction, transformation depends on validation, and publication depends on transformation. This can be pictured as a directed graph: tasks are nodes, and arrows show what must finish before downstream work starts. Independent branches can run in parallel. For example, two source tables might be copied at the same time, while a join waits for both copies.
A completed task is not always the same as usable data. A file transfer can exit successfully but deliver an empty file; a query can complete while reading yesterday’s partition. Put checks at boundaries where bad input would spread: confirm the expected partition exists, required fields are present and outputs have a plausible shape. Decide in advance whether a failed check blocks downstream tasks or merely raises a warning. That choice should reflect how the output will be used, not just whether the scheduler reports success.
Retry temporary failures without repeating damage
Retries help when a task fails for a temporary reason, such as a brief network interruption or a busy service. Set a limited number of attempts and a delay between them; increasing the delay after repeated failures can give a recovering service time to respond. Do not retry every error blindly. A missing required field or an invalid query is unlikely to fix itself, and repeated attempts may waste resources or obscure the underlying problem.
Design tasks so rerunning them has a predictable result. If a transformation writes the summary for a particular day, it can replace that day’s output rather than append duplicate rows each time. This is an example of idempotent behavior: repeating the same operation produces the intended state without multiplying its effects. Tasks that send notifications, charge an account or modify an external system need particular care because their effects may be hard to undo. Where appropriate, use stable run identifiers and check whether an action has already succeeded before repeating it.
Schedule runs and verify readiness
A schedule answers when the orchestrator should consider starting a run. It does not guarantee that the input has arrived. If the sales summary is scheduled for early morning but its source export is late, starting the transformation on time could produce an incomplete result. A readiness check can wait for a file, partition or upstream completion signal, with a timeout and an alert if the input never arrives. The schedule sets the expected cadence; the readiness check protects the work.
Give each run a clear data interval, such as the day of transactions it processes, rather than relying only on the time the task starts. This makes delayed runs and backfills easier to reason about. A backfill reruns the pipeline for past intervals, perhaps after fixing a transformation error. Check whether each task can safely process an older interval and whether publishing those results will replace, merge with or duplicate existing data. Also account for time zones and daylight-saving changes when a calendar day defines the interval.
Make failures understandable and recovery deliberate
A useful pipeline shows more than a red failure indicator. For every run, record the intended interval, task status, attempt count and enough logs to identify what failed. Alerts should point to the affected pipeline and step, while avoiding sensitive data in messages. Teams can then distinguish a late source, a temporary service problem and a persistent data-quality issue. Clear ownership matters too: someone should know who can inspect the source and who can approve republishing an output.
Start with a small dependency graph and add complexity only when it solves a real need. For the sales summary, that might mean one scheduled run, a source-readiness check, validation before transformation, bounded retries for the copy step and a replaceable daily output. Test what happens when an input is late, a task fails halfway through or a past day must be rerun. Good orchestration is less about making every run succeed automatically than about making the pipeline’s behavior predictable when conditions are imperfect.


